Series: “Election Forecasting: Between Statistics, Politics, and Uncertainty” — Election Forensics
A new series: less fortune-telling, more understanding
How many votes will Serbia's Student List win? How much support will the electoral list led by Aleksandar Vučić attract? Which parties will cross the electoral threshold, who will form the next government, and perhaps the most politically sensitive question of all: whose opinion polls should we believe?
In Serbia's increasingly polarised political debate, the answer sometimes appears surprisingly simple. Believe the poll whose results you like. Question the others. And when a particularly inconvenient result appears, call it a “fake poll”. Unfortunately, statistical methodology is somewhat less accommodating.
This article launches a new weekly series on my Election Forensics blog, dedicated to the methods, assumptions, possibilities, and limitations of forecasting election results. Over the coming weeks, we will explore what opinion polls actually measure, how surveys can be combined, how forecasting models work, why turnout matters, how uncertainty should be quantified, and how projected votes become parliamentary seats. We will also consider a particularly challenging question: how should forecasting operate when political competition takes place on an uneven playing field?
The series draws on my forthcoming book, Forecasting Elections: Data, Models, and Electoral Uncertainty, currently in preparation. Before finalising the manuscript, I want to present some of its central arguments to a wider audience. I hope that comments, criticism, and questions will help improve the final version of the book.
The articles are intended for researchers, statisticians, political scientists, journalists, election observers, civil society organisations, students, and interested readers who simply want to understand what lies behind the percentages appearing in political headlines. No advanced statistical background will be required.
Nor will I attempt to identify who possesses the most reliable electoral crystal ball. If someone has one, perhaps they could at least publish its methodology.
From election forensics to election forecasting
My interest in election forecasting developed naturally from earlier work on election forensics. Election forensics primarily looks backwards, examining what election data can tell us after votes have been cast and counted. Are patterns of turnout and voting statistically unusual? Do some polling stations or municipalities deserve closer examination? What conclusions are supported by the available evidence, and what would require additional investigation?
Forecasting reverses the direction of analysis. Instead of beginning with known results and asking how they arose, we begin with incomplete information about voters, political parties, institutions, and the electoral environment and attempt to estimate what may happen in the future. The two activities are different, but share important methodological principles: data quality, transparent assumptions, reproducibility, and responsible treatment of uncertainty.
An important distinction concerns the interpretation of discrepancies. If an election result differs substantially from a forecast, that difference alone does not establish electoral manipulation. Equally, a remarkably accurate forecast does not demonstrate that the election was perfectly conducted. Forecasting cannot replace election forensics, nor should election forensics be transformed into a retrospective exercise in predicting results that are already known.
Four numbers, four apparently competing realities
Imagine a parliamentary election scheduled for one month from now. Within a few days, four organisations publish different figures concerning the same hypothetical electoral list, List A.
The first reports 41% support, based on an opinion poll conducted during the previous week. The second combines several recent polls and estimates current underlying support at 42%. The third suggests that, if turnout reaches 65%, List A could receive approximately 39% of the vote. The fourth forecasts an election-day result of approximately 40%, with an 80% predictive interval ranging from 36% to 44%, and a 68% probability that List A will finish first.
Which organisation is correct? In a typical television discussion, this question might quickly produce allegations of political bias, disputes about who commissioned the research, and confident predictions about the election's outcome. However, there is another possibility: all four analyses might be methodologically defensible.
The reason is that they are not estimating the same quantity. The first is a poll. The second is an estimate of current underlying electoral support. The third is a conditional scenario, while the fourth is an election forecast. These differences determine how the figures should be interpreted, whether they can legitimately be compared, and how their performance should eventually be evaluated.
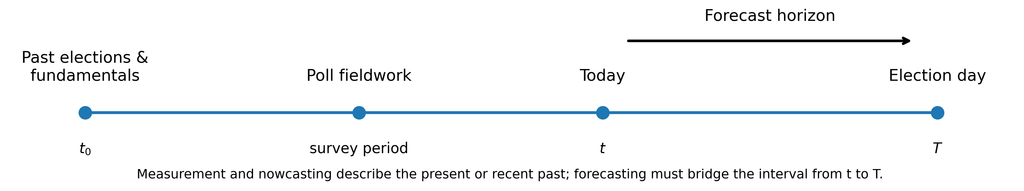
[FIGURE 1 — Four numbers, four different analytical products: 41% poll; 42% estimate of current support; 39% conditional scenario; 40% election forecast.]
Three questions before believing any number
Before evaluating an electoral percentage, we should ask three elementary questions. What is being estimated? Is the number a percentage of all adults, decided respondents, likely voters, or actual votes expected on election day? When does the estimate apply? Does it refer to the survey's fieldwork period, the present political situation, or a future election date? Under what conditions does it hold? Does it assume a particular level of turnout, a specific configuration of electoral lists, or a particular pattern of mobilisation?
These questions may appear elementary, but overlooking them can fundamentally change the meaning of a reported result. Suppose a survey reports that 40% of decided respondents support a particular electoral list. This does not mean that 40% of all adult citizens support it. Some citizens may remain undecided, some may intend not to vote, and others may refuse to reveal their preference.
Consequently, two surveys may both be well conducted and still produce different percentages because their denominators differ. The denominator is rarely the most exciting component of a television headline. Nevertheless, it matters.
What does an opinion poll actually measure?
An opinion poll is not a miniature election held several weeks in advance. It is a measurement of expressed attitudes or preferences among a defined population during a particular period. Its results depend on how respondents were selected, who participated, how questions were formulated, how interviews were conducted, how non-response was handled, and how the resulting observations were weighted.
Even an excellent poll cannot automatically reveal the future. Imagine that a survey accurately measures electoral preferences four weeks before an election. During the following month, a major political scandal occurs, a new coalition is formed, or previously disengaged voters become politically mobilised. The eventual election result differs substantially from the earlier survey.
Does this mean the poll was fraudulent? Not necessarily. The poll may have measured the political situation accurately at the time. What changed was the situation itself.
An everyday analogy helps illustrate the point. If a thermometer correctly records 18°C today and the temperature falls to 11°C three weeks later, the earlier measurement does not become incorrect. Political preferences are, of course, more complicated than temperature, and political temperatures in Serbia have recently been particularly high. Nevertheless, measurement is not the same as forecasting.
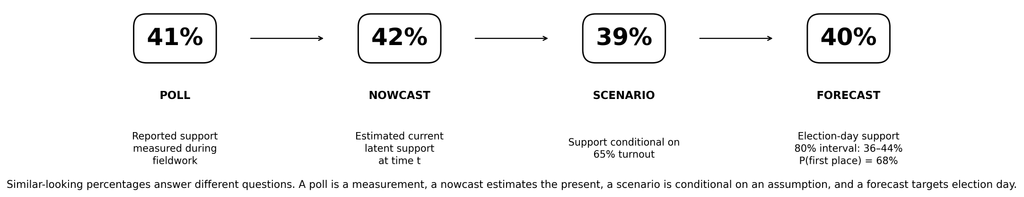
[FIGURE 2 — Timeline showing historical electoral information, polling fieldwork, the present date, and election day.]
Serbia offers a useful real-world example
Consider two recently published surveys concerning Serbia's anticipated parliamentary elections. CRTA and Stanford University's Democracy Action Lab conducted a face-to-face survey between 10 and 24 June 2026, based on a sample of 2,324 adult citizens. Among decided voters, it reported 44.9% support for the Student List and 35.7% for the Serbian Progressive Party (SNS).
A September survey by Faktor Plus, conducted between 16 and 20 September among 986 respondents, produced a markedly different picture: 48.6% for the electoral list led by Aleksandar Vučić and 37.1% for the Student List. A Faktor Plus representative subsequently clarified in a public interview that these percentages referred to decided voters.
One survey showed the Student List ahead; the other showed the Vučić-led list ahead. This is precisely the kind of disagreement that can dominate Serbia's political discussion. The temptation is to ask which organisation manipulated its data, but a more useful starting point is to examine the measurement process.
The surveys were conducted approximately three months apart, with different sample sizes and different levels of publicly available methodological explanation. Before treating their results as directly comparable, we need to establish whether they measured the same populations, used comparable questions, defined decided voters consistently, included the same electoral options, and applied similar procedures for weighting and handling undecided respondents.
Some differences may reflect genuine changes in public opinion. Others may result from methodological variation or measurement error. Without an appropriate analysis, we cannot determine how much of the observed disagreement belongs to each explanation.
The larger CRTA sample does not automatically make its estimates superior. Sample size matters, but representativeness and systematic sources of error matter too. Similarly, an estimate favouring the governing parties cannot be accepted or dismissed merely because of the perceived political orientation of the polling organisation.
Another distinction is equally important: the quality of the original research is not identical to the quality of its media presentation. CRTA, for example, published detailed methodological documentation, including information about sampling and weighting. Some media reports of the Faktor Plus survey included considerably less information, while further methodological clarification appeared in subsequent interviews.
These differences do not establish which organisation has the more accurate estimates. They demonstrate why complete, accessible documentation matters.
When “fake polling” replaces methodological criticism
The expression “fake polls” has become part of Serbia's political vocabulary. Some pro-government media have used such language to challenge surveys whose results favour opposition or student-led political actors.
Informer has published articles describing CRTA's and other organisations’ research as false or manipulated. In one column, local election results across several municipalities were used to challenge national opinion surveys. Pink published allegations concerning CRTA, BIRODI, and NSPM, including references to supposedly fabricated or unreliable research.
Such allegations should not be accepted merely because they are stated forcefully. At the same time, fairness requires acknowledging that some of these articles raise methodological objections, including questions about sampling, commissioning organisations, data collection, and transparency. Those questions are legitimate when supported by evidence, and the absence of essential methodological information is a valid reason to criticise any survey.
But an organisation's alleged political alignment, its funding sources, or the political inconvenience of its results do not, by themselves, constitute statistical evidence of fabrication. Nor can a collection of local election results automatically be treated as a representative sample of national voting intentions. Local political competition, turnout, demographic composition, and the timing of elections can all affect comparability.
If our purpose is to expose poor statistical reasoning, we should avoid reproducing it in the process.
One methodological standard for everyone
A central principle of this series will be that polling organisations should be judged by their evidence and methods, not by whether their conclusions favour the government or its opponents. Commercial polling organisations such as Faktor Plus and Ipsos should face the same requirements for methodological transparency as CRTA, BIRODI, NSPM, and other organisations publishing election-related research or scenarios.
These organisations do not necessarily produce identical analytical products. Some publish opinion polls; others may publish scenarios, estimates, or modelling exercises. That is precisely why classification must precede evaluation.
Researchers have a responsibility to explain how their results were obtained, what they measure, and what cannot legitimately be concluded from them. Journalists and editors have a related responsibility: not to transform a carefully qualified estimate into an unsupported political prediction.
Consider the difference between these statements: “Among decided respondents, 44.9% currently support a particular electoral list”; “44.9% of Serbian citizens support that list”; and “The list will win 44.9% in the election.” They do not mean the same thing. The first refers to a specific survey population and period, the second changes the denominator, while the third turns a measurement into a forecast.
Similarly, the claim that an electoral list would obtain an “absolute majority” requires clarification. Does this refer to a majority of votes, a majority of parliamentary seats, or a hypothetical election held immediately? The relationship between votes and seats in Serbia depends on electoral thresholds, the allocation formula, and the performance of other lists.
Even when the original numerical estimate is correct, an imprecise interpretation can create an unsupported political conclusion. This matters particularly in a polarised environment, where incomplete or selective presentation of opinion polls can amplify distrust and political conflict. A survey does not have to be fraudulent for its presentation to become misleading.
A nowcast is not an election forecast
Return to our four hypothetical percentages. Suppose recent polls place List A at 39%, 42%, and 44%. Instead of selecting whichever survey we prefer, we might combine the available information to estimate the underlying level of electoral support.
A statistical model could account for sample sizes, fieldwork dates, survey modes, weighting procedures, and systematic differences between polling organisations. It might estimate current support at 42%. This is an estimate of the present electoral situation, often called a nowcast.
The underlying support is described as latent because it cannot be observed directly and perfectly. We infer it from imperfect measurements. A nowcast may provide a more informative assessment of current support than any individual survey, but it is still not necessarily a forecast of election-day results.
If an election is six weeks away, preferences may change, turnout intentions may shift, and unexpected political developments may occur. An election forecast must take an additional step from current information into an uncertain future. That requires assumptions or models describing possible changes between today and election day.
Scenarios: the importance of one small word
Suppose another analyst estimates that List A would receive approximately 39% of the vote if turnout reached 65%. Those final words change the meaning of the result.
The analysis is a conditional scenario. It asks what might happen under specified conditions. Scenarios can be extremely useful: they can show how higher turnout, increased participation among younger voters, or mobilisation of previous abstainers might affect electoral outcomes.
But a scenario does not automatically estimate the probability that its assumptions will actually be realised. A forecast, by contrast, attempts to describe what is likely to happen, including uncertainty about future conditions. A scenario is not scientifically inferior to a forecast; it answers a different question.
The problem arises when a conditional scenario is publicly presented as an unconditional prediction. The word “if” is not a decorative element that can safely be removed from the headline.
Methodology is not decoration
If we want a more responsible public debate about elections in Serbia, we need to change how we read and communicate survey results. Instead of immediately asking whose numbers we should believe, we should first establish what was measured, when, how, among whom, and under which assumptions.
It is not enough to publish a methodology section as a formality. Polling organisations should explain the meaning of their results, their limitations, and the conclusions that cannot be drawn from them. This educational responsibility is particularly important when the audience is not familiar with survey methods.
Media organisations should preserve those qualifications rather than sacrificing them for dramatic headlines. A headline may be necessary, but ten attractive words should not erase the limitations of months of research.
The next article will take us one step further. Even when we understand what an electoral percentage means, how confident should we be in it? We will examine why identical estimates of 41% can imply very different forecasts, and why a list expected to receive 3.1% may face more politically consequential uncertainty than one expected to receive 40%.
For now, the principal lesson is straightforward: a poll is not a crystal ball, a scenario is not a promise, and a percentage without methodological context may be little more than a number with a microphone.
Sources and further reading
- CRTA — New Survey: They Believe in Democracy, Not in the Government, July 2026 (Serbian).
- Politika — Vučić-led List at 48.6%, Student List at 37.1%, September 2026 (Serbian).
- N1 — What Do the Latest Opinion Polls Tell Us?, interview with representatives of Faktor Plus and BIRODI, October 2026 (Serbian).
- Informer — Column on Local Elections and Opinion Polls, March 2026 (Serbian).
- Pink — Allegations Concerning CRTA, BIRODI, and NSPM Research (Serbian).
- Lewis-Beck, M. S. (2005). Election Forecasting: Principles and Practice.

Director of Wellington based My Statistical Consultant Ltd company. Retired Associate Professor in Statistics.
Has a PhD in Statistics and over 45 years experience as a university professor, consultant, international researcher and government advisor.